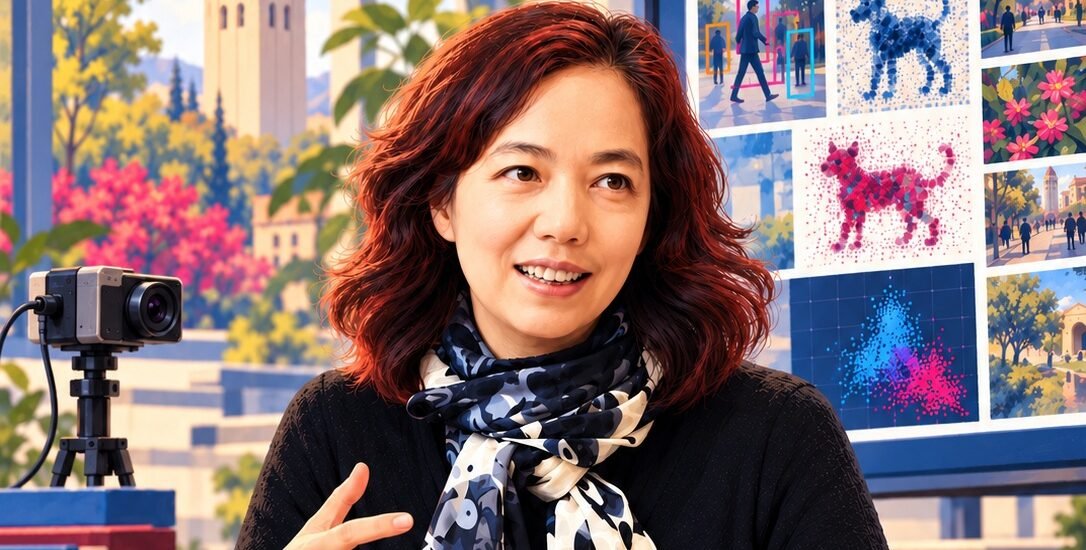
Fei-Fei Li is a computer scientist, entrepreneur and institution-builder whose work helped establish the data infrastructure on which modern computer vision and deep learning accelerated. She led the creation of ImageNet, a dataset of more than 14 million annotated images that changed how researchers approached machine learning; founded educational and research institutions including AI4ALL and the Stanford Institute for Human-Centered Artificial Intelligence; and in 2024 co-founded World Labs to pursue a new technical frontier she calls spatial intelligence. In September 2026, AMD agreed to acquire World Labs in an all-stock transaction valued at approximately $8.2 billion. When the transaction closes, Li is expected to join AMD as Executive Vice President and Chief Scientist, reporting to CEO Lisa Su. Stanford Profiles
Category: Pioneer
Field: Artificial Intelligence · Computer Vision · Machine Learning · Spatial Intelligence · AI Education
The computer scientist who helped give modern AI the data it needed to see, then built institutions around who develops artificial intelligence, how it serves people, and what machines might learn to understand next.
At a Glance
Li’s career can be read as a sequence of infrastructure problems. Early computer-vision systems lacked enough structured data to learn from the visual world, so she led the creation of ImageNet. The AI field lacked sufficiently broad participation, so she helped establish an education pipeline that became AI4ALL. Universities were developing increasingly powerful AI systems without an institution designed to integrate technical research with medicine, law, economics, ethics and public policy, so she co-founded Stanford HAI. Current AI systems can generate language and images but remain limited in their ability to reason about and act within three-dimensional environments, so she co-founded World Labs to develop spatially intelligent world models. Across each phase, Li’s work has moved beyond building individual algorithms toward building the datasets, organizations and research platforms through which other people can build. Princeton Engineering
| Category | Details |
|---|---|
| Born | 1976 · Beijing, China; raised in Chengdu |
| Country | China · United States |
| Field | Artificial intelligence, computer vision, machine learning, robotics, spatial intelligence and AI-enabled healthcare |
| Known For | ImageNet; Stanford HAI; AI4ALL; World Labs; human-centered AI |
| Education | B.A. Physics, Princeton University, 1999; M.S. Electrical Engineering, Caltech, 2001; Ph.D. Electrical Engineering, Caltech, 2005 |
| Major Roles / Organizations | Stanford University; Stanford AI Lab; Stanford HAI; AI4ALL; Google Cloud; World Labs |
| Current Work | Sequoia Professor of Computer Science at Stanford; Founding Director and Senior Fellow at Stanford HAI; Special Advisor on AI to Stanford’s president; co-founder and CEO of World Labs |
| Major Milestone | Led the creation of ImageNet, one of the foundational datasets of modern deep learning |
| Next Role | Expected to become AMD Executive Vice President and Chief Scientist after AMD’s pending acquisition of World Labs |
| GDT Category | Pioneer |
Li has published more than 400 scientific papers and is an elected member of the National Academy of Engineering, National Academy of Medicine and American Academy of Arts and Sciences. Her major recognitions include the 2025 Queen Elizabeth Prize for Engineering, the 2024 VinFuture Prize, the 2023 Intel Lifetime Achievement Award and election as an ACM Fellow. Stanford Profiles
Why She’s a Girls Do That Champion
Modern artificial intelligence is often explained through algorithms.
That explanation is incomplete.
Machine learning systems depend on an interaction among at least three forms of infrastructure:
algorithms
computing power
data
The breakthroughs associated with modern deep learning emerged when all three became available at sufficient scale.
Li’s central contribution was to recognize the importance of the third component before much of the field did.
In the mid-2000s, prestige in computer vision largely came from designing better models. Datasets were comparatively small. Building a very large dataset was labor-intensive, expensive and, to some researchers, intellectually uninteresting.
Li argued that the scale of the learning material itself was a scientific problem.
A child does not learn what a dog is by seeing one dog.
Human visual intelligence is built through enormous exposure to variation.
Different dogs.
Different angles.
Different lighting.
Different environments.
Different backgrounds.
Different levels of obstruction.
If machines were expected to recognize objects robustly, they would need something closer to that scale of experience.
The result was ImageNet.
Years later, the dataset became the arena in which deep neural networks demonstrated a dramatic leap in image-recognition performance. The event helped shift machine learning toward the neural-network methods that now underpin much of contemporary artificial intelligence. Princeton Engineering
But Li’s relevance to Girls Do That extends beyond one technical breakthrough.
Her career repeatedly shows a particular kind of building:
identify a missing layer in a system, then build the layer.
ImageNet was missing data infrastructure.
AI4ALL addressed the talent pipeline.
Stanford HAI addressed institutional coordination.
World Labs is addressing spatial reasoning.
That is not simply a research career.
It is systems construction.
Her Story
Beijing, Chengdu and New Jersey
Fei-Fei Li was born in Beijing in 1976 and grew up in Chengdu.
She developed an early interest in science, particularly physics.
In 1992, when she was 15, Li moved with her family from China to Parsippany, New Jersey.
The transition substantially changed the family’s circumstances.
Li arrived speaking limited English. Her parents had professional and educational experience that did not transfer cleanly into the American labor market. They eventually operated a dry-cleaning business, while Li worked in restaurants and helped support the family business alongside school. Princeton Alumni
Her academic ability was already evident.
A high-school mathematics teacher, Bob Sabella, spent lunch periods helping her learn advanced calculus. Li later received a full scholarship to Princeton University. She has recalled being sufficiently surprised by the offer that she asked multiple school advisers to verify that she had understood the acceptance letter correctly. Stanford HAI
The family’s economic circumstances did not disappear when she entered Princeton.
She continued helping operate the dry-cleaning business while completing her studies. Princeton University
That coexistence is important to the chronology.
The future AI researcher was not moving through science in isolation from ordinary operating realities.
She was simultaneously studying physics and helping run a small family business.
Physics
Li graduated from Princeton in 1999 with high honors in physics.
Physics attracted her because of the scale of the questions.
What is matter?
What is time?
How does the universe work?
But another question increasingly interested her:
How does intelligence work?
At the California Institute of Technology, where she pursued graduate study in electrical engineering, Li began moving toward the intersection of computer vision, neuroscience and cognition.
She earned a master’s degree in electrical engineering in 2001 and a Ph.D. in electrical engineering in 2005. Stanford Profiles
Her research increasingly focused on one of the most computationally difficult things human beings do almost effortlessly:
see.
Seeing Is Not Photography
A camera can capture pixels.
That is not the same as understanding what those pixels represent.
A child looking at an image may immediately recognize:
a dog,
a chair,
a road,
a person,
a glass sitting close to the edge of a table.
The child can also infer relationships.
The glass might fall.
The person may be reaching toward it.
The road continues behind the vehicle.
This appears effortless because human visual intelligence has developed through biological evolution and enormous accumulated experience.
For a computer, the problem is different.
Pixels begin as numerical values.
Meaning has to be learned.
Li’s research would increasingly focus on closing that gap between capturing visual information and understanding a visual world.
Before ImageNet
When Li began working in computer vision, research datasets were relatively small.
Researchers generally competed on model design.
A new algorithm might be trained and tested against hundreds or thousands of images organized into a limited number of categories.
Li began questioning whether the problem was partly upstream.
Perhaps computer-vision systems were not only constrained by their algorithms.
Perhaps they were data-starved.
The hypothesis was simple but expensive:
if a machine is expected to understand the visual world, expose it to the visual world at scale.
That required a different kind of research project.
Not another model.
A dataset.
A very large one.
WordNet Becomes ImageNet
In 2007, Li returned to Princeton as an assistant professor.
Her office happened to be near that of Christiane Fellbaum, a linguist who had spent decades working on WordNet.
WordNet organizes words into networks of semantic relationships.
A concept such as dog belongs to broader conceptual structures:
animal.
mammal.
canine.
Different breeds then sit below it.
The system provided a map of language.
Li saw the possibility of creating a corresponding map of images.
She would take WordNet’s conceptual hierarchy and populate its categories with visual examples.
The name followed naturally:
ImageNet. Princeton Engineering
The idea dramatically increased the scale of the computer-vision problem.
Instead of building a dataset around a few categories, Li’s team wanted thousands.
Instead of dozens or hundreds of images per concept, they wanted roughly a thousand.
The goal was not simply to create a large folder of photographs.
It was to create a structured visual ontology.
Building ImageNet
The operational problem quickly became enormous.
Images had to be found.
Categorized.
Verified.
Rejected when inaccurate.
Assigned to appropriate concepts.
And the process had to work across millions of examples.
Li, Jia Deng, Kai Li, Olga Russakovsky and a broader research team eventually organized the work around large-scale crowdsourcing.
At its peak, the effort involved roughly 50,000 workers across 167 countries processing a vast pool of candidate images. Stanford later described the effort as involving the filtering of approximately a billion images before ImageNet reached more than 15 million categorized images across roughly 22,000 object categories. Stanford Engineering
By 2010, the core dataset contained more than 14 million annotated images. Princeton Engineering
The scale mattered because the field was about to acquire two other ingredients:
much more powerful computing hardware
and
neural-network architectures capable of learning from large datasets.
ImageNet supplied the third.
Data as Infrastructure
The strategic insight behind ImageNet was that a dataset could function as research infrastructure.
Once the dataset existed, thousands of researchers did not have to independently create millions of labeled images before testing an idea.
They could work against a shared benchmark.
That creates comparability.
If Team A and Team B both train models on the same dataset and perform against the same test set, researchers can measure which approach works better.
The dataset therefore did two things simultaneously.
It provided training material.
And it created a market-like mechanism for comparing technical performance.
That second function became particularly important.
The ImageNet Challenge
In 2010, Li and collaborators launched the ImageNet Large Scale Visual Recognition Challenge.
Research teams could train systems against ImageNet and compete on standardized image-recognition tasks.
For the first two years, improvements were incremental.
Then came 2012.
A University of Toronto team led by Geoffrey Hinton, with graduate students Alex Krizhevsky and Ilya Sutskever, entered a deep convolutional neural network later known as AlexNet.
Its performance dramatically exceeded competing approaches.
The result changed the trajectory of artificial intelligence research.
Neural networks were not new.
Many of the underlying concepts had existed for decades.
But the combination had changed:
large-scale data + GPUs + neural networks.
ImageNet gave the network enough organized visual experience to demonstrate what the approach could do.
Princeton researchers later described the competition as a turning point at which much of the field began to accept that deep learning worked at scale. Princeton Engineering
The subsequent years brought rapid improvements in computer vision.
Convolutional neural networks spread into:
image classification,
object detection,
medical imaging,
autonomous systems,
face recognition,
video analysis,
robotics,
and eventually the broader deep-learning architectures used throughout modern AI.
ImageNet did not independently create the deep-learning revolution.
It provided one of its essential pieces of infrastructure.
What ImageNet Changed
ImageNet changed more than benchmark scores.
It helped alter the field’s assumptions about the importance of data.
Before large-scale machine learning, a common research orientation was:
design an intelligent algorithm and give it data.
The emerging deep-learning paradigm increasingly became:
design a sufficiently capable learning architecture, provide enormous amounts of structured data and compute, and allow useful representations to emerge through training.
That shift now appears throughout contemporary AI.
Large language models use enormous text corpora.
Multimodal models use images, video, speech and text.
Robotics systems increasingly learn from simulation and demonstrations.
The basic lesson remains recognizable:
scale and structure of training experience matter.
The Limits of a Dataset
The influence of ImageNet also exposed a second lesson.
Datasets are not neutral representations of reality.
People choose:
what categories exist,
which examples represent them,
how labels are defined,
what is excluded,
and which distinctions are treated as meaningful.
As computer vision moved from laboratories into real-world systems, researchers identified problems involving bias, representation, privacy and offensive categories within large image datasets, including ImageNet.
Li and collaborators subsequently participated in research specifically examining these limitations.
A 2020 paper, “Towards Fairer Datasets,” examined ImageNet’s person hierarchy and identified problems arising from outdated terminology inherited from WordNet, attempts to visually represent categories that should not have been treated as visual categories, and unequal demographic representation.
The ImageNet team later removed 2,702 problematic synsets from the people subtree and released privacy-oriented updates including face-blurred versions of challenge data. ImageNet
The evolution matters.
ImageNet demonstrated the power of data infrastructure.
Its shortcomings demonstrated that data governance is also infrastructure.
What goes into a training set can shape what comes out of a model.
Stanford
Li joined the Stanford faculty in 2009.
From 2013 to 2018, she served as Director of the Stanford Artificial Intelligence Laboratory, one of the central academic institutions in the history of artificial intelligence. Stanford Profiles
Her research expanded beyond object recognition into broader visual intelligence:
scene understanding,
human activity recognition,
visual relationships,
robotics,
and the relationship between biological and machine perception.
She also began spending increasing attention on two problems outside conventional model performance.
Who was building AI?
And what was AI being built for?
The AI Talent Pipeline
By the mid-2010s, artificial intelligence was beginning to accelerate commercially.
The people developing the technology, however, remained drawn from a comparatively narrow talent pool.
Li viewed this as both an equity problem and a technical problem.
If AI systems increasingly influence medicine, education, transportation, employment and information, the people designing those systems make choices about which problems matter and how they are defined.
A field drawing from a narrow population risks narrowing the problems it notices.
Her response began with a summer programme.
SAILORS
In 2015, Li, Olga Russakovsky and Rick Sommer created Stanford Artificial Intelligence Laboratory’s Outreach Summer programme, known as SAILORS.
Its initial focus was introducing high-school girls to artificial intelligence.
Students encountered AI not as a distant graduate-level research field but as something they could learn, question and eventually build.
The programme expanded.
In 2017, the broader nonprofit AI4ALL was formally established. AI4ALL
Its mandate broadened beyond one Stanford programme.
Universities across the United States developed AI4ALL summer programmes.
The organization later expanded into undergraduate technical training and career preparation.
By October 2026, AI4ALL reported that it had trained more than 8,000 emerging AI professionals in responsible AI over nearly a decade. AI4ALL
The programmatic logic is similar to ImageNet.
The intervention is not:
find one exceptional student.
It is:
build a pipeline capable of producing cohorts.
Why Diversity Becomes a Technical Question
Li has repeatedly connected inclusion to the design of AI itself.
At the launch of Stanford HAI, she summarized the problem directly:
“The creators of AI need to represent humanity.” Stanford HAI
The proposition has a systems logic.
People choose datasets.
People define objective functions.
People determine what counts as an error.
People choose where AI is deployed.
People determine what risks are acceptable.
People decide who benefits.
Increasing the range of people involved therefore changes the range of experience available during technological design.
Google Cloud
From 2017 to 2018, while on sabbatical from Stanford, Li served as a Vice President at Google and Chief Scientist of AI/ML at Google Cloud. Stanford Profiles
The role placed her inside a different layer of the AI system.
Academic research develops methods.
Cloud infrastructure distributes those methods to organizations.
The distinction matters.
A research paper may demonstrate that an AI technique works.
A cloud platform turns the capability into infrastructure that thousands of organizations can access.
The period also coincided with rapid commercialization of machine learning as companies began integrating computer vision, speech recognition and predictive systems into mainstream software products.
Li returned to Stanford in 2018.
Her next major project was again institutional.
Stanford Human-Centered AI
In March 2019, Stanford launched the Institute for Human-Centered Artificial Intelligence, or HAI.
Li became its founding co-director alongside former Stanford provost John Etchemendy.
The premise was that artificial intelligence had become too consequential to remain solely an engineering problem.
HAI was designed to connect researchers across:
computer science,
medicine,
law,
business,
economics,
education,
humanities,
social science,
policy,
and ethics.
Its stated mission is to advance AI research, education, policy and practice in ways that improve the human condition. Stanford HAI
The institution rests on three broad propositions.
AI should be inspired by human intelligence.
AI should augment rather than simply replace people.
AI development should be evaluated by its impact on human beings and society.
This represented another expansion in Li’s unit of analysis.
ImageNet asked:
How do we make machines see better?
HAI asks:
What happens to people when machines become more capable?
Human-Centered AI
Human-centered AI does not mean making artificial intelligence less technically ambitious.
It changes what counts as successful technical development.
Accuracy matters.
So do:
privacy,
safety,
human agency,
accessibility,
fairness,
economic effects,
and the relationship between automated systems and human judgment.
Li’s work increasingly positioned AI as infrastructure that has to be governed and designed around those wider effects.
In 2024, speaking at Princeton, she summarized the principle:
“It should be used for humans and should be governed by humans.” Princeton University
In 2026, Stanford reorganized HAI alongside its data-science initiative. Li moved into a university-wide role as Special Advisor on AI to Stanford President Jonathan Levin, while becoming co-chair of HAI’s advisory council and continuing as a Stanford professor and senior fellow. Stanford News
AI in Healthcare
One major application of Li’s human-centered research agenda has been healthcare.
Hospitals generate enormous amounts of clinical information, but much of what happens around a patient is not captured cleanly in structured data.
A nurse may enter a room.
A patient may attempt to leave a bed.
A clinical workflow may deviate from protocol.
A caregiver may be overloaded.
An older adult living at home may gradually change how they move through everyday activities.
Li and collaborators have investigated what they call ambient intelligence: combinations of sensors and machine-learning systems capable of interpreting activity within physical environments while attempting to preserve privacy. Stanford Profiles
Potential applications include:
monitoring patient safety,
understanding clinical workflows,
reducing documentation burden,
supporting older adults living independently,
and identifying health-relevant behavioral changes.
The research also exposes a recurring tension in AI deployment.
A system capable of observing a physical environment can potentially improve safety.
The same capability creates serious privacy and consent questions.
Technical capability and human governance therefore have to develop together.
The Next Technical Problem
By the early 2020s, artificial intelligence had made enormous progress in language.
Large language models could:
write,
summarize,
translate,
reason across text,
generate code,
and increasingly work across images and audio.
Li believed another fundamental capability remained underdeveloped.
Humans do not experience reality primarily as strings of text.
We exist in three-dimensional space.
We understand:
distance,
depth,
geometry,
motion,
objects,
physical relationships,
and consequences.
We know instinctively that a glass positioned at the edge of a table can fall.
A robot must learn that.
This is the problem Li describes as spatial intelligence.
Spatial Intelligence
Visual recognition asks:
What am I looking at?
Spatial intelligence asks a broader set of questions:
Where is it?
How is it positioned relative to something else?
What happens if it moves?
How might I interact with it?
What exists outside the current camera angle?
How might this environment change over time?
How can I create a coherent new environment?
The difference is important.
Recognizing a chair is computer vision.
Understanding where the chair is, navigating around it, moving it safely and predicting what happens if it falls requires a richer model of physical space.
At TED in 2024, Li summarized the shift:
“Simply seeing is not enough. Seeing is for doing and learning.” TED
The argument became the foundation of her next company.
World Labs
In 2024, Li co-founded World Labs with Justin Johnson, Ben Mildenhall and Christoph Lassner.
The company’s objective is to build AI systems capable of perceiving, generating, reasoning about and interacting with three-dimensional worlds. World Labs
World Labs describes these systems as world models.
Where a language model learns statistical structure across words and tokens, a world model aims to learn structure across:
objects,
spaces,
geometry,
motion,
viewpoints,
physical relationships,
and time.
Potential applications extend well beyond image generation.
Spatial models could support:
robotics,
game development,
architecture,
simulation,
film production,
industrial design,
scientific research,
augmented reality,
virtual reality,
and training environments for embodied AI.
Financing World Labs
The company attracted substantial capital almost immediately.
In September 2024, World Labs announced approximately $230 million in initial financing from investors including Andreessen Horowitz, NEA and Radical Ventures, with participation from technology investors including AMD, Intel and Nvidia. Reuters
In February 2026, the company raised another $1 billion.
Investors included:
AMD,
Nvidia,
Autodesk,
Fidelity,
Emerson Collective,
and Sea,
among others. World Labs
The financing reflected a broader shift in the AI market.
The first major wave of generative AI had been built predominantly around language and two-dimensional media.
Investors and technology companies were increasingly interested in systems capable of modeling the physical world.
Marble
World Labs’ first major product was Marble.
Marble is a multimodal world model capable of generating persistent three-dimensional environments from:
text,
images,
video,
and rough 3D layouts.
Users can move through the generated environment rather than simply viewing a flat image or short generated video.
They can also edit, expand and combine worlds. World Labs
The distinction is technical.
A generated image provides one viewpoint.
A coherent world model has to maintain enough internal spatial consistency that a user can move the camera and continue encountering a plausible environment.
That makes the underlying problem substantially more complex.
The model must infer what exists beyond the original viewpoint.
From ImageNet to World Models
There is a direct intellectual line between ImageNet and World Labs.
ImageNet asked machines to learn the identity of things in images.
Later computer-vision systems learned relationships among those things.
Spatial intelligence asks systems to model the world containing them.
The progression looks approximately like this:
pixels → objects → scenes → relationships → 3D environments → interaction
Each layer requires richer representations.
ImageNet helped accelerate the first major leap.
World Labs is Li’s attempt to build around the later ones.
World Labs as a Business
World Labs also represents a significant change in Li’s career.
ImageNet was academic infrastructure.
AI4ALL is nonprofit educational infrastructure.
HAI is university infrastructure.
World Labs is a venture-backed technology company.
That means the research must eventually become:
products,
developer tools,
commercial applications,
customer value,
and scalable infrastructure.
Marble was one expression of that transition.
World Labs also began developing tools and APIs through which external developers could incorporate world-generation technology into their own products.
In July 2026, the company expanded further into robotics through the acquisition of SceniX, extending its work toward simulation and physical AI. World Labs
Then came AMD.
The $8.2 Billion AMD Agreement
On September 28, 2026, AMD announced a definitive agreement to acquire World Labs for approximately $8.2 billion in stock.
The transaction remains subject to regulatory approvals and customary closing conditions and is expected to close by the end of 2026. AMD Newsroom
The strategic logic is unusually interesting.
World Labs builds AI models.
AMD builds the computing infrastructure on which AI models run.
Bringing the two together creates a feedback loop between:
model research,
software,
chips,
systems,
and future computing architecture.
As world models become more computationally intensive, researchers gain better understanding of what future hardware needs to do.
Hardware designers can then optimize systems around emerging model workloads.
After the transaction closes, Li is expected to become AMD Executive Vice President and Chief Scientist, reporting directly to CEO Lisa Su. World Labs’ research team is expected to continue developing frontier AI models inside AMD. AMD Newsroom
For Li, the move would mark another expansion in system scale.
ImageNet operated at the data layer.
Google exposed her to cloud distribution.
World Labs operates at the model layer.
AMD adds the compute layer.
Building the Full Stack
The phrase full stack is useful for understanding the arc of Li’s career.
An AI system requires multiple layers:
Talent
Researchers and engineers capable of building systems.
AI4ALL addresses who enters the field.
Data
Structured examples from which models can learn.
ImageNet helped establish large-scale visual training data.
Models
Algorithms capable of extracting useful representations.
Li’s academic work spans computer vision, machine learning and robotics.
Research Institutions
Structures that coordinate disciplines and determine research agendas.
Stanford HAI operates here.
Applications
Healthcare, robotics, creative tools and other use cases.
Li’s Stanford research and World Labs work operate here.
Compute
The processors and systems required to train and operate increasingly sophisticated models.
The planned AMD role moves directly into this layer.
Across four decades, her career has therefore expanded from studying intelligence to influencing many of the systems through which artificial intelligence is produced.
The Book
In 2023, Li published The Worlds I See: Curiosity, Exploration, and Discovery at the Dawn of AI.
The book combines two histories.
One is personal:
immigration,
family,
poverty,
education,
science,
and belonging.
The other is technical:
the development of computer vision and the emergence of modern AI.
The combination is consistent with Li’s broader intellectual position.
Artificial intelligence is not separate from the people who build it.
The history of the technology is also the history of:
the researchers,
their institutions,
their incentives,
their values,
their failures,
and the societies in which the systems are deployed.
Princeton selected the memoir as its 2024 Pre-read, distributing it to incoming students. Princeton University
Recognition
Li’s influence has increasingly been recognized across scientific and engineering institutions.
She is an elected member of:
The National Academy of Engineering
The National Academy of Medicine
The American Academy of Arts and Sciences
and a Fellow of the Association for Computing Machinery. Stanford Profiles
In 2025, she was one of seven researchers awarded the Queen Elizabeth Prize for Engineering for foundational contributions to modern machine learning.
The cohort included:
Yoshua Bengio,
Bill Dally,
Geoffrey Hinton,
John Hopfield,
Jensen Huang,
Yann LeCun,
and Fei-Fei Li. Queen Elizabeth Prize for Engineering
She has also received the VinFuture Prize, Intel Lifetime Achievement Award, Princeton’s Woodrow Wilson Award and distinguished alumni recognition from both Princeton and Caltech.
The awards reflect something broader than citation counts.
Li’s work influenced not just a research subfield, but the technical architecture through which an entire era of machine learning developed.
What Fei-Fei Li Built
The institutions and projects associated with Li operate at very different scales, but they solve connected problems.
| System | Problem | Intervention |
|---|---|---|
| ImageNet | Computer-vision models lacked visual training data at sufficient scale | Built a structured dataset containing millions of labeled images |
| ImageNet Challenge | Researchers lacked a common large-scale performance benchmark | Created a standardized competition for comparing visual-recognition systems |
| AI4ALL | AI talent pipelines excluded large portions of the population | Built education and career pathways into artificial intelligence |
| Stanford HAI | AI consequences exceeded the boundaries of computer science | Created an interdisciplinary institution connecting technology with medicine, business, law, humanities and society |
| Healthcare AI research | Important clinical activity remains difficult to observe and structure | Developed ambient-intelligence approaches for understanding physical care environments |
| World Labs | AI systems remain weak at understanding and interacting with 3D environments | Builds world models for spatial intelligence |
| AMD role | Frontier models and computing infrastructure are increasingly interdependent | Connects model research directly with hardware, software and AI compute architecture |
The pattern is consistent.
Li rarely treats a missing capability as an isolated feature.
She treats it as an infrastructure problem.
From Dataset Builder to Institution Builder
A conventional account of Fei-Fei Li’s career might describe her as the creator of ImageNet.
That is accurate but incomplete.
The broader pattern is more useful.
She has repeatedly moved one layer outward from the original technical problem.
Computer vision led to datasets.
Datasets led to questions about representation.
Representation led to education pipelines.
Technical progress led to questions about societal impact.
Those questions led to Stanford HAI.
Visual intelligence led to spatial intelligence.
Spatial intelligence led to World Labs.
World Labs is now moving into a global semiconductor and computing company.
The unit of impact has expanded each time.
Milestones
| Year | Milestone |
|---|---|
| 1976 | Born in Beijing, China; grows up in Chengdu |
| 1992 | Moves to the United States with her family at age 15 and settles in New Jersey |
| 1999 | Graduates from Princeton University with high honors in physics |
| 2001 | Earns M.S. in electrical engineering from Caltech |
| 2005 | Earns Ph.D. in electrical engineering from Caltech |
| 2005 | Begins faculty career at the University of Illinois Urbana-Champaign |
| 2007 | Joins Princeton University as assistant professor |
| 2007 | Begins developing the concept that becomes ImageNet |
| 2009 | ImageNet research is formally published |
| 2009 | Joins Stanford University |
| 2010 | Launches the ImageNet Large Scale Visual Recognition Challenge with collaborators |
| 2012 | AlexNet’s ImageNet Challenge performance demonstrates the power of GPU-trained deep neural networks |
| 2013 | Becomes Director of the Stanford Artificial Intelligence Laboratory |
| 2015 | Co-founds SAILORS, the Stanford programme that becomes the foundation for AI4ALL |
| 2015 | Gives TED talk explaining ImageNet and the challenge of machine vision |
| 2017 | AI4ALL formally launches as a nonprofit |
| 2017–2018 | Serves as Google Vice President and Chief Scientist of AI/ML at Google Cloud |
| 2018 | Completes term as Director of Stanford AI Lab |
| 2019 | Co-founds Stanford Institute for Human-Centered Artificial Intelligence |
| 2019–2021 | ImageNet team develops fairness and privacy improvements to the dataset |
| 2023 | Publishes The Worlds I See |
| 2023 | Receives Intel Lifetime Achievement Award |
| 2024 | Co-founds World Labs |
| 2024 | World Labs launches with approximately $230 million in financing |
| 2024 | Delivers TED talk outlining spatial intelligence as a major next frontier in AI |
| 2024 | Receives VinFuture Prize |
| 2025 | Receives Queen Elizabeth Prize for Engineering |
| 2025 | World Labs launches Marble, its generative 3D world model |
| 2026 | World Labs raises $1 billion in new financing |
| 2026 | AI4ALL reports having trained more than 8,000 emerging AI professionals over nearly a decade |
| 2026 | Becomes Stanford’s Special Advisor on AI and co-chair of HAI’s advisory council |
| September 2026 | AMD agrees to acquire World Labs for approximately $8.2 billion |
| Pending 2026 close | Expected to join AMD as Executive Vice President and Chief Scientist |
In Her Own Words
“The creators of AI need to represent humanity.”
— Fei-Fei Li, Stanford HAI
“Simply seeing is not enough. Seeing is for doing and learning.”
— Fei-Fei Li, TED 2024
“It should be used for humans and should be governed by humans.”
— Fei-Fei Li, Princeton University
Read · Watch · Listen
Read
The Worlds I See: Curiosity, Exploration, and Discovery at the Dawn of AI
Li’s memoir connects her family’s immigration story, her development as a scientist, the creation of ImageNet and the emergence of contemporary artificial intelligence.
In the Hallways of Princeton, a Fascination With the Human Mind Unlocked the Power of Deep Learning — Princeton Engineering
A detailed reconstruction of how WordNet, ImageNet and the ImageNet Challenge contributed to the rise of deep learning.
Fei-Fei Li: A Candid Look at a Young Immigrant’s Rise to AI Trailblazer — Stanford HAI
A concise account of Li’s immigration, education and scientific development.
Our Story — AI4ALL
The institutional history of the education programme that began at Stanford in 2015 and developed into a national AI nonprofit.
World Labs
The research and product platform Li co-founded to develop spatial intelligence.
AMD to Acquire World Labs to Advance the Future of AI Compute
AMD’s September 2026 announcement detailing the proposed $8.2 billion transaction and Li’s expected future role.
Watch
How We’re Teaching Computers to Understand Pictures — TED 2015
Li explains computer vision, ImageNet and the technical challenge of moving from pixels toward visual understanding.
With Spatial Intelligence, AI Will Understand the Real World — TED 2024
Nine years after her first TED talk, Li explains the progression from image recognition toward systems capable of reasoning about and interacting with three-dimensional worlds.
Listen
The Frontier of Spatial Intelligence — a16z
A long-form discussion with Li and World Labs co-founder Justin Johnson about world models, visual intelligence and why 3D reasoning represents a different technical problem from language modeling.
Go Deeper
Fei-Fei Li — Stanford University
https://profiles.stanford.edu/fei-fei-li
ImageNet
https://www.image-net.org/
Stanford Institute for Human-Centered Artificial Intelligence
https://hai.stanford.edu/
AI4ALL
https://ai-4-all.org/
Stanford AI4ALL
https://ai4all.spcs.stanford.edu/
World Labs
https://www.worldlabs.ai/
Marble — World Labs
https://www.worldlabs.ai/blog/marble-world-model
The Worlds I See
https://us.macmillan.com/books/9781250897930/theworldsisee/
Sources & Further Reading
APA 7th Edition
Advanced Micro Devices, Inc. (2026, September 28). AMD to acquire World Labs to advance the future of AI compute. https://newsroom.amd.com/news/amd-acquire-world-labs/
AI4ALL. (n.d.). Our story. https://ai-4-all.org/about/our-story/
AI4ALL. (2026, October 2). AI4ALL’s next chapter. https://ai-4-all.org/ai4alls-next-chapter/
ImageNet. (2019, September 17). Towards fairer datasets: Filtering and balancing the distribution of the people subtree in the ImageNet hierarchy. https://www.image-net.org/update-sep-17-2019.php
ImageNet. (2021, March 11). ImageNet update. https://www.image-net.org/update-mar-11-2021.php
Li, F.-F. (2023). The worlds I see: Curiosity, exploration, and discovery at the dawn of AI. Flatiron Books. https://us.macmillan.com/books/9781250897930/theworldsisee/
Princeton University. (2024, February 23). The Worlds I See by AI visionary Fei-Fei Li ’99 selected as Princeton Pre-read. https://www.princeton.edu/news/2024/02/23/worlds-i-see-ai-visionary-fei-fei-li-99-selected-princeton-pre-read
Princeton University. (2024, February 26). At Alumni Day, Princeton honors computer scientist Fei-Fei Li ’99 and ornithologist John Fitzpatrick. https://www.princeton.edu/news/2024/02/26/alumni-day-princeton-honors-computer-scientist-fei-fei-li-and-ornithologist-john
Princeton University. (2025, February 6). John Hopfield and Fei-Fei Li win Queen Elizabeth Prize as pioneers in modern AI. https://www.princeton.edu/news/2025/02/06/john-hopfield-and-fei-fei-li-win-queen-elizabeth-prize-pioneers-modern-ai
Princeton University School of Engineering. (2025, September 22). In the hallways of Princeton, a fascination with the human mind unlocked the power of deep learning. https://engineering.princeton.edu/news/2025/09/22/hallways-princeton-fascination-human-mind-unlocked-power-deep-learning
Stanford Institute for Human-Centered Artificial Intelligence. (2019, March 24). Stanford’s new institute will unite humanities and computer science to study, guide and develop human-centric artificial intelligence. https://hai.stanford.edu/news/stanfords-new-institute-will-unite-humanities-and-computer-science-study-guide-and-develop
Stanford Institute for Human-Centered Artificial Intelligence. (2023, November 7). Fei-Fei Li: A candid look at a young immigrant’s rise to AI trailblazer. https://hai.stanford.edu/news/fei-fei-li-candid-look-young-immigrants-rise-ai-trailblazer
Stanford University. (2026, May 4). Stanford merges AI and data science efforts under single institute. https://news.stanford.edu/stories/2026/05/stanford-merges-hai-data-science
TED. (2015, March). Fei-Fei Li: How we’re teaching computers to understand pictures. https://www.ted.com/talks/fei_fei_li_how_we_re_teaching_computers_to_understand_pictures
TED. (2024, April). Fei-Fei Li: With spatial intelligence, AI will understand the real world. https://www.ted.com/talks/fei_fei_li_with_spatial_intelligence_ai_will_understand_the_real_world
World Labs. (2025, November 12). Marble: A multimodal world model. https://www.worldlabs.ai/blog/marble-world-model
World Labs. (2026, February 18). World Labs announces new funding. https://www.worldlabs.ai/blog/funding-2026
World Labs. (2026, September 28). World Labs is joining AMD. https://www.worldlabs.ai/blog/amd-announcement
Build the Infrastructure Others Build On
Explore the Girls Do That Pioneer Collection, celebrating women and girls who turn ideas into technologies, organizations and systems that expand what other people can create.
Every collection helps fund a Girls Do That Club for the next generation.